

Blog
Insights & updates from our experts


Resolve plant floor and IT issues before they disrupt production.

Stay audit-ready while resolving issues and reducing operational risk.
Resolve issues quickly with an AI-powered system that automates ticketing.
Unifiy IT, HR, Facilities, Finance, and more on a single, AI-powered service platform.
Simplify on-call scheduling, automate escalations, and reduce burnout.
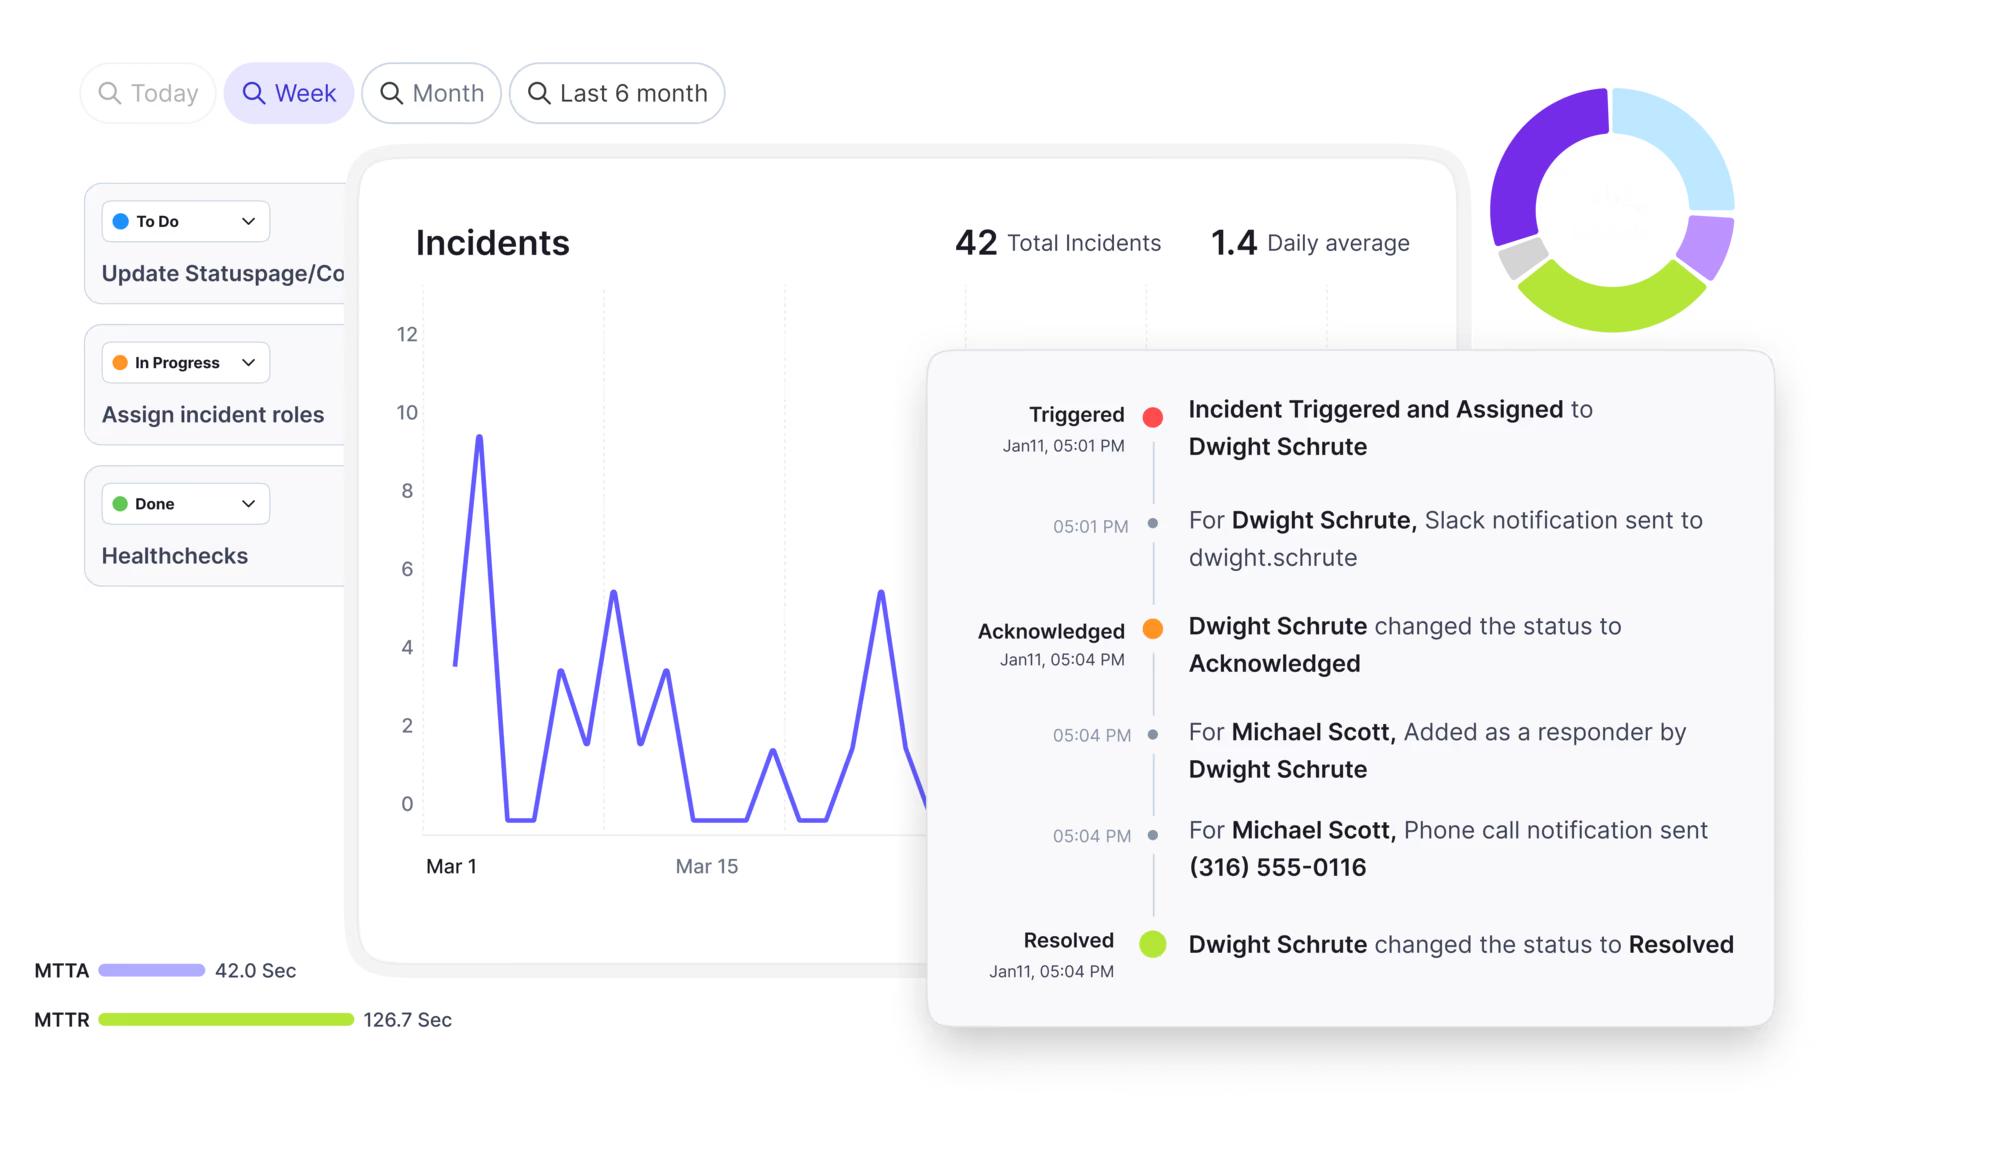
Automate postmortems, AI summaries, and post-incident workflows
Create, organize, and continuously improve your knowledge base to find the right answers with Sera AI.
We're here to help
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
Resolve issues quickly with an AI-powered system that automates ticketing.
Unifiy IT, HR, Facilities, Finance, and more on a single, AI-powered service platform.
Simplify on-call scheduling, automate escalations, and reduce burnout.
Automate postmortems, AI summaries, and post-incident workflows
Create, organize, and continuously improve your knowledge base to find the right answers with Sera AI.
Resolve plant floor and IT issues before they disrupt production.
Stay audit-ready while resolving issues and reducing operational risk.

Detect, respond, and resolve incidents fast to cut downtime and MTTR.

Keep your store online, even during your biggest sales moments.
Protect patient data and resolve issues fast, so care teams stay focused on care.
Standardize service delivery across every store and channel.

We are here to help 24/7

Connect with other Xurrent Users

Get insights and tips on how to get the most out of Xurrent

Apps, APIs, and updates

Xurrent service functionality

Eliminate manual tasks, optimize workflows, and deliver faster resolutions.
Learn how organizations have reduced downtime, improved 50% MTTA & MTTR, and cut costs with Xurrent IMR.
Discover Xurrent IMR's quick support, bidirectional integrations with Jira and Slack, and more cohesive incident response capabilities compared to Opsgenie.
Understand why users value Xurrent IMR for its intuitive interface, efficient incident alerting, customizable On-call schedules, and escalations.
Over the years there have been a bunch of great talks on site reliability and incident response. Below are a few we thought stood out(in no specific order) and is defintely worth a peek.
02 Jul 2020

Most AI SREs are pattern matchers trained on public data. They know what a memory leak looks like in the abstract. They don't know that your payments-api has a flaky liveness probe everyone ignores, that the checkout team owns the retry policy, or that the last three "database incidents" were actually cache misconfigurations. That knowledge lives in your postmortems, your Slack channels, and the heads of two senior engineers.
Most vendors will tell you ITSM implementation takes six months to a year — but modern, configuration-first platforms have rewritten the math entirely. See what real implementations look like in 2026, and why a long rollout is now a choice, not a given.