

Blog
Insights & updates from our experts


Resolve plant floor and IT issues before they disrupt production.

Stay audit-ready while resolving issues and reducing operational risk.
Resolve issues quickly with an AI-powered system that automates ticketing.
Unifiy IT, HR, Facilities, Finance, and more on a single, AI-powered service platform.
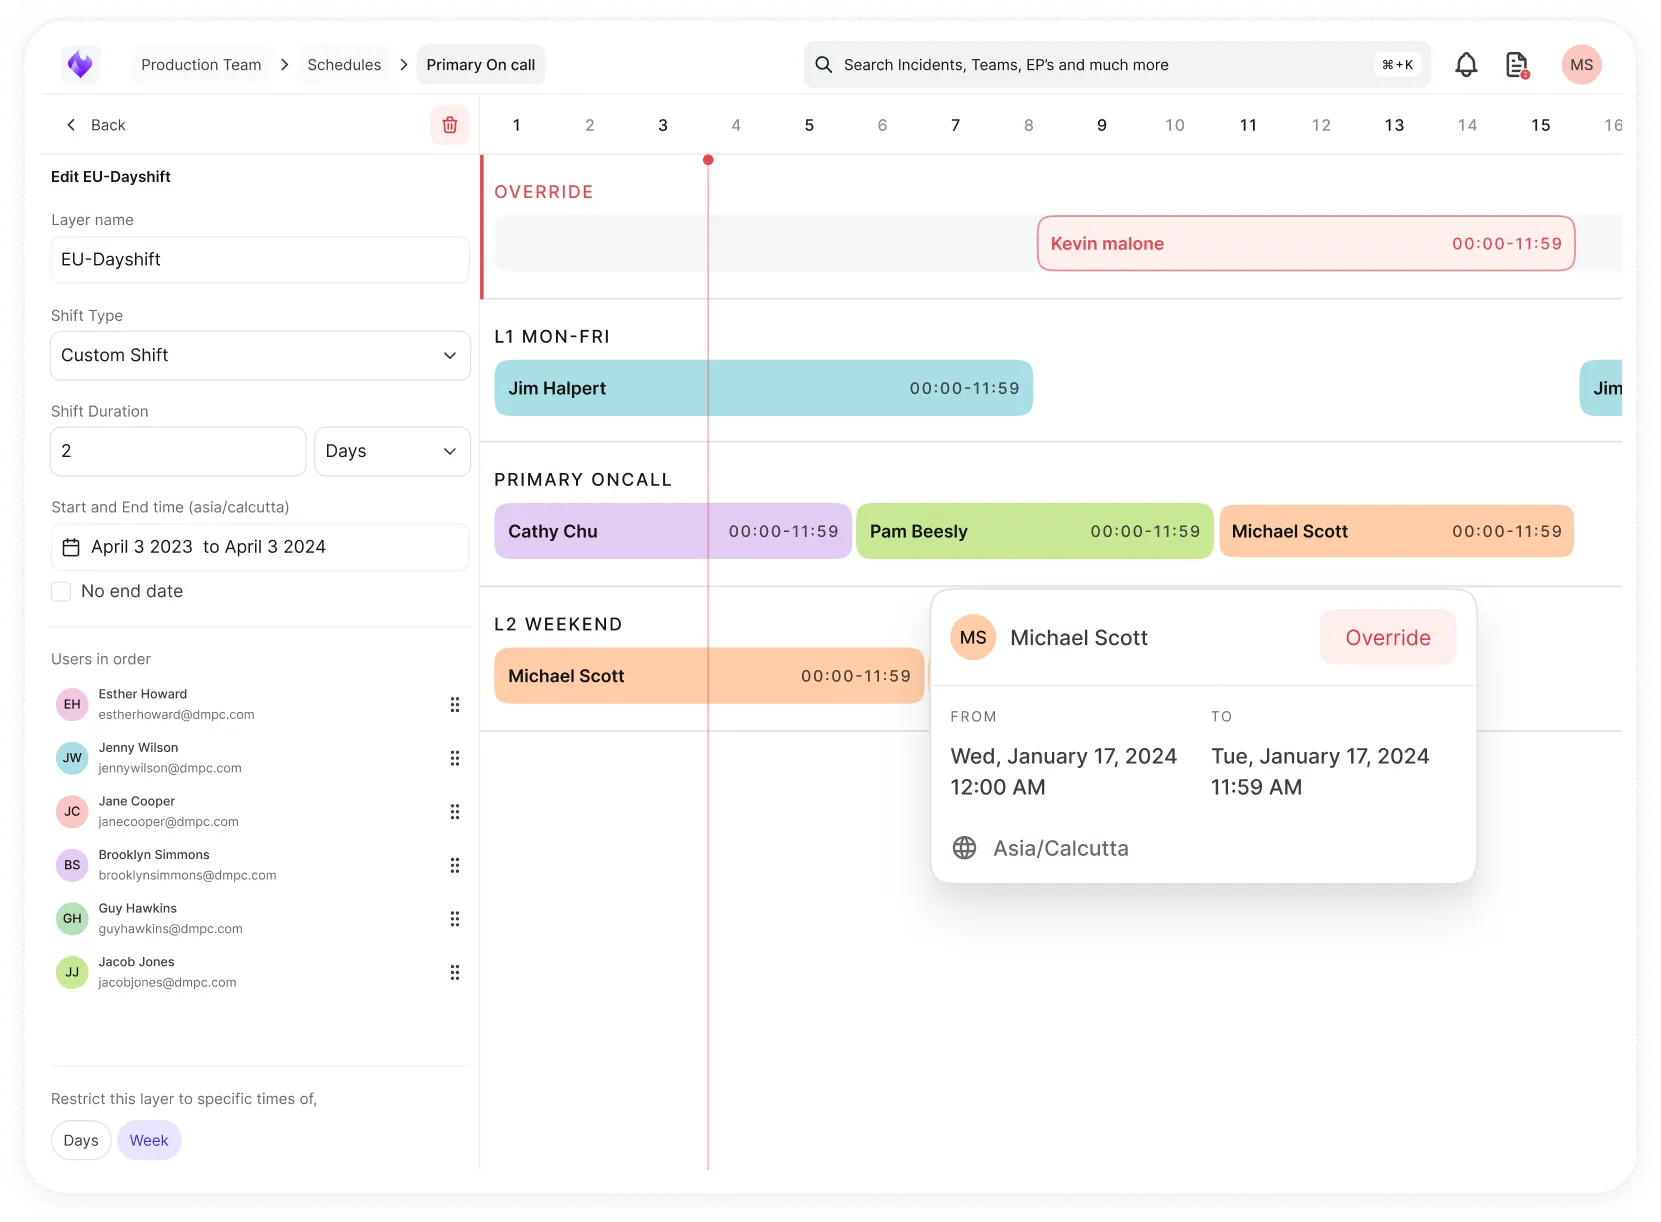
Simplify on-call scheduling, automate escalations, and reduce burnout.
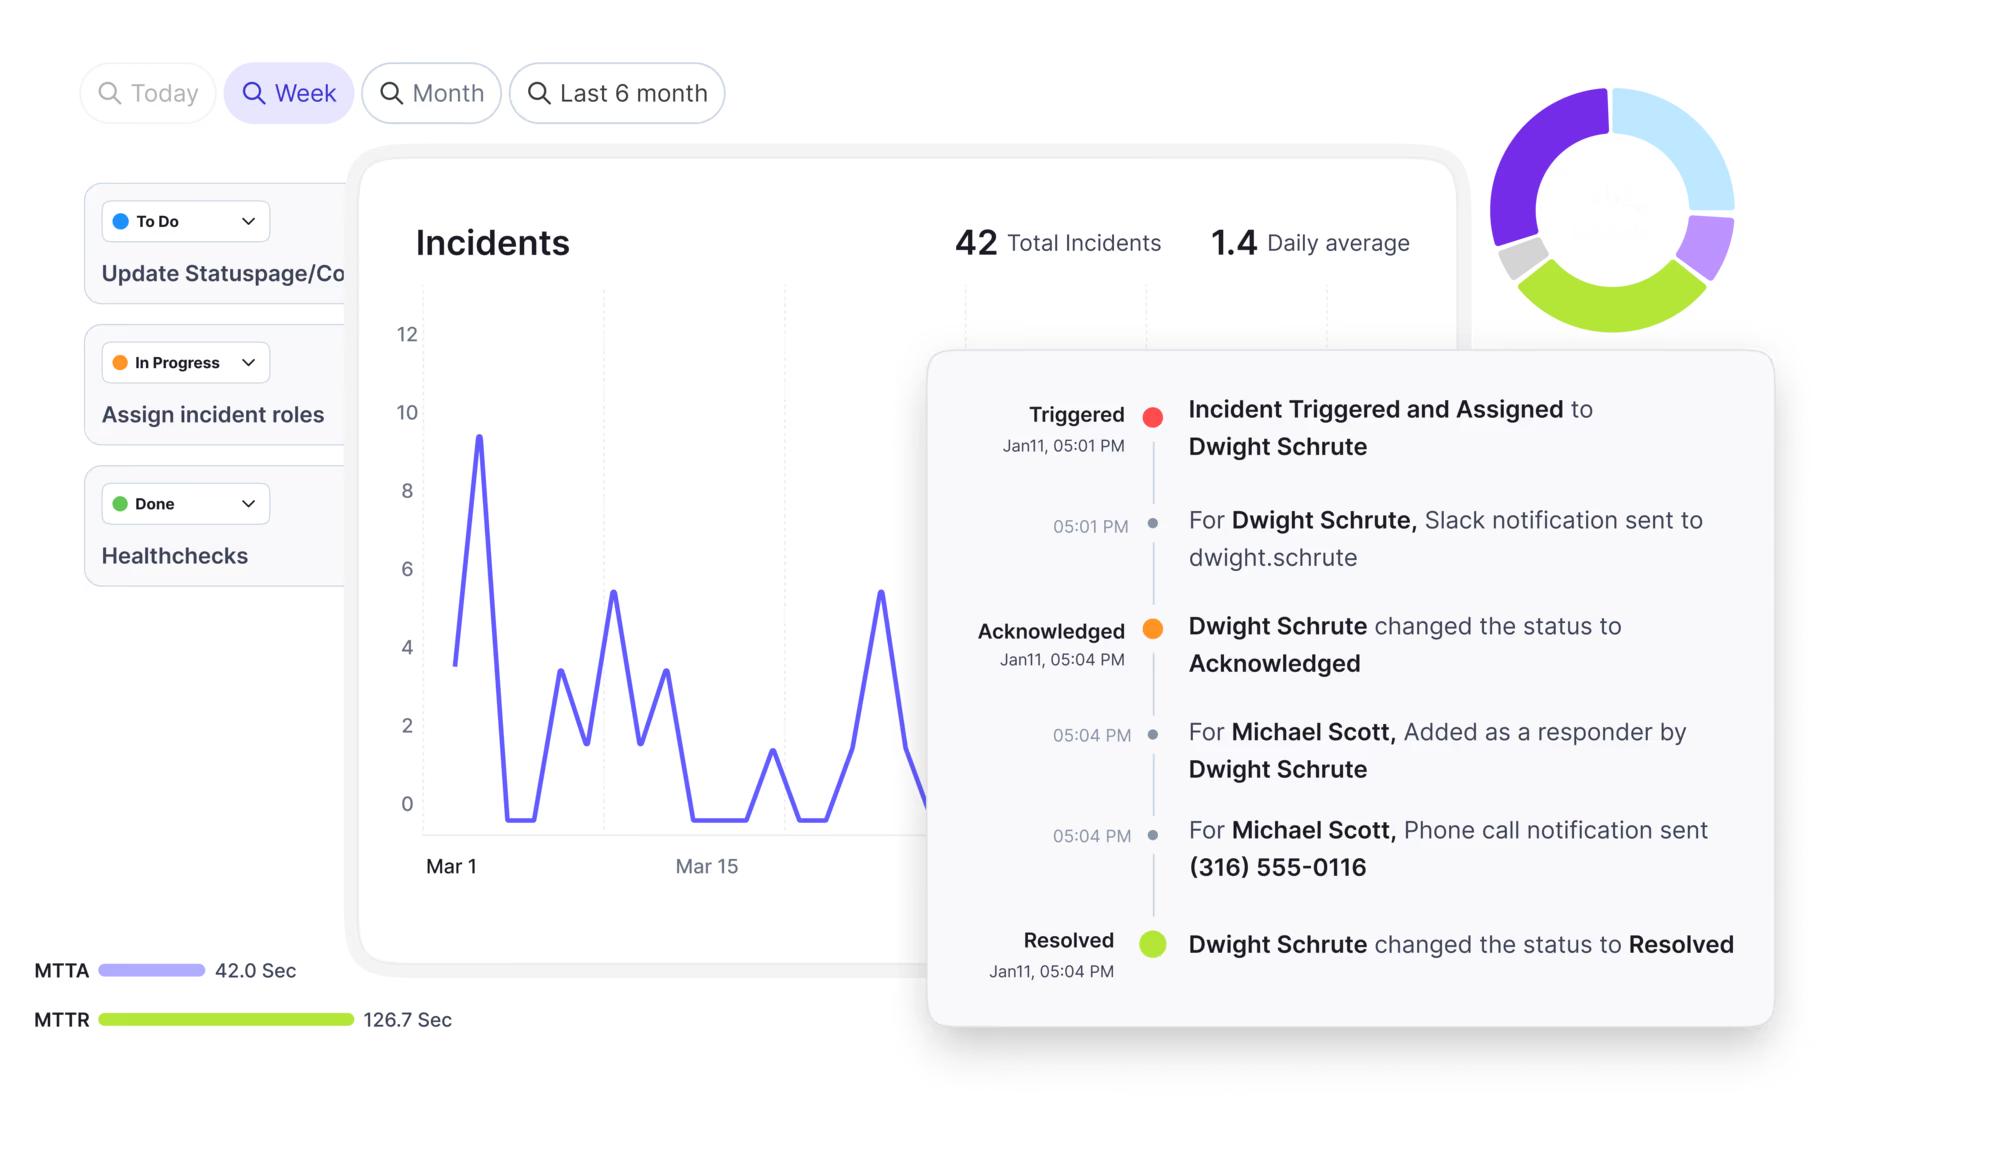
Automate postmortems, AI summaries, and post-incident workflows
Create, organize, and continuously improve your knowledge base to find the right answers with Sera AI.
We're here to help
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
The integration with Atlassian Jira using the Xurrent Integration Service is
Resolve issues quickly with an AI-powered system that automates ticketing.
Unifiy IT, HR, Facilities, Finance, and more on a single, AI-powered service platform.
Simplify on-call scheduling, automate escalations, and reduce burnout.
Automate postmortems, AI summaries, and post-incident workflows
Create, organize, and continuously improve your knowledge base to find the right answers with Sera AI.
Resolve plant floor and IT issues before they disrupt production.
Stay audit-ready while resolving issues and reducing operational risk.

Detect, respond, and resolve incidents fast to cut downtime and MTTR.

Keep your store online, even during your biggest sales moments.
Protect patient data and resolve issues fast, so care teams stay focused on care.
Standardize service delivery across every store and channel.

We are here to help 24/7

Connect with other Xurrent Users

Get insights and tips on how to get the most out of Xurrent

Apps, APIs, and updates

Xurrent service functionality

Eliminate manual tasks, optimize workflows, and deliver faster resolutions.
Learn how organizations have reduced downtime, improved 50% MTTA & MTTR, and cut costs with Xurrent IMR.
Discover Xurrent IMR's quick support, bidirectional integrations with Jira and Slack, and more cohesive incident response capabilities compared to Opsgenie.
Understand why users value Xurrent IMR for its intuitive interface, efficient incident alerting, customizable On-call schedules, and escalations.
Listen to the latest episode where host Jim Hirschauer sits down with Steve Flanders, Senior Director of Engineering at Splunk and a founding member of OpenTelemetry. They dig into the real cost of high cardinality data, why the OTel Collector should work as a control plane, and why SLO based alerts beat threshold based ones every time.
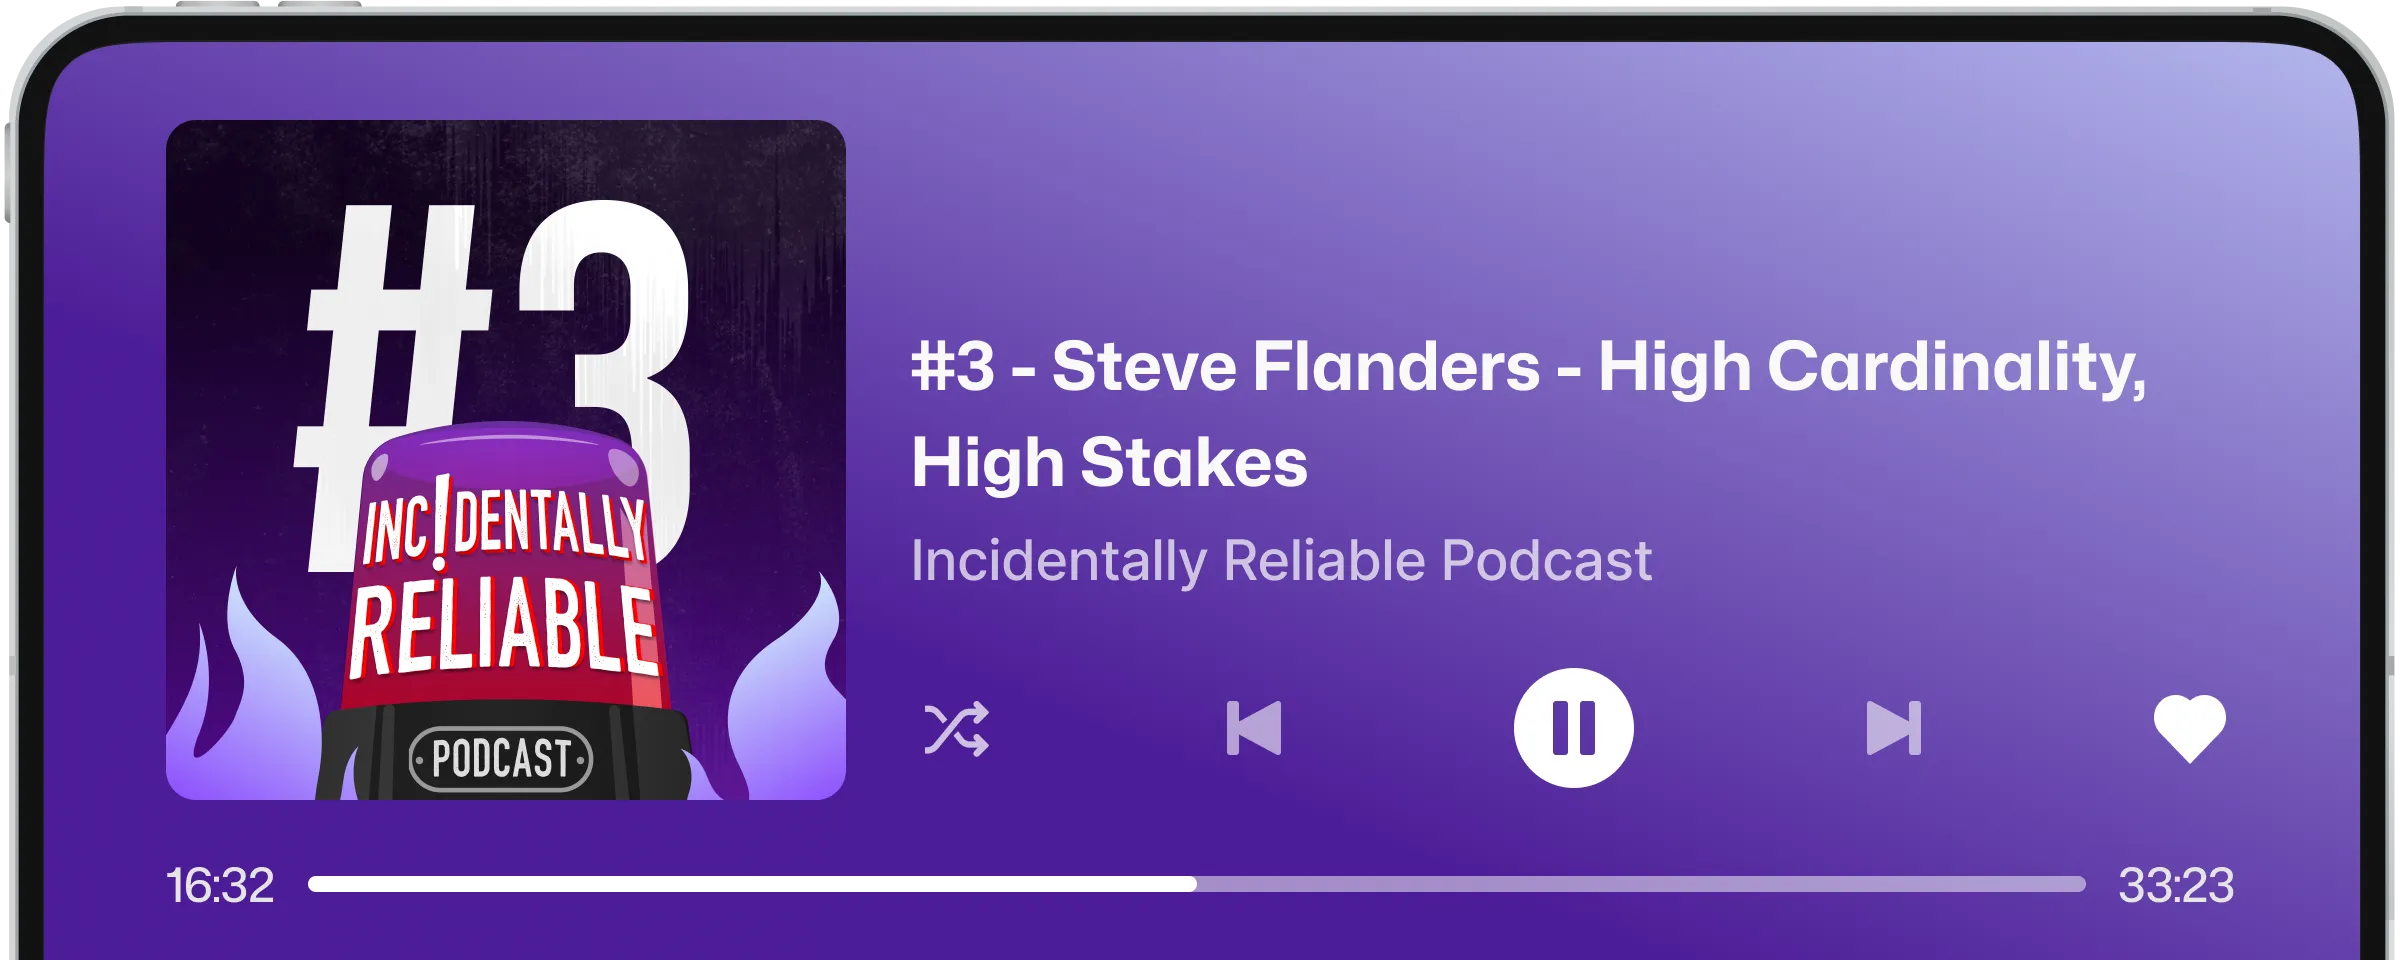
More data does not mean more clarity, sometimes it just means more noise. In this episode, our guest Steve Flanders, Senior Director of Engineering at Splunk and a founding member of OpenTelemetry, joins Jim to unpack the real cost of high cardinality data, why the OpenTelemetry Collector works best as a control plane and not just a forwarder, and why SLO based alerts beat threshold based ones every time. It is a practical look at how teams can cut through the noise and only page for what actually matters.
Reliability means knowing when to trust the fix, not just how fast it happens. In this episode, we sit down with our guest Zahan Parekh, founder of Gimic, to talk through runbooks, human in the loop decision making, and what it takes to keep AI accountable in production. Jim and Zahan discuss why runbooks go stale, the difference between deterministic and probabilistic automation, and why governance, not just good intentions, is what keeps AI safe near prod.
Reliability is about fixing things, not just resolving them. In this season premiere, we take a trip down memory lane with Vishwa to uncover the story behind Zenduty and how the "Incidentally Reliable" podcast began. Jim and Vishwa discuss the transition to Xurrent, the "needle in the haystack" problem in modern observability, and why culture—not just code—is the key to true reliability.
In this episode, Sudarshan shares his experience leading high-performing SRE and infrastructure teams at Rippling, Twilio, Walmart, and Epsilon. He talks about reducing CI/CD costs by 60 percent, cutting on-call alerts by 65 percent, and the mindset required to build resilient systems.
In this episode, Madhu Rawat (CTO, Xurrent) sits down with Sakshi — Co-founder and Head of Engineering at Kapstan, with leadership experience at Sumo Logic and UpGrad. They discuss the evolution of observability, building for scale, the role of AI in incident management, and what it means to lead engineering teams through change.
Peek into their journey so far, manoeuvred nightmares, their war-room stories and opinions on the current state of the space.
When I joined Xurrent as CEO in February, I made a commitment to myself before I made any commitments publicly: I would listen before I led. I would get in front of customers, sit down with our partners, and spend real time with the incredible team that built this platform — before I said a word about where I thought we were going.
We had the pleasure of meeting Ponmani Palanisamy, a Staff Site Reliability Engineer at LinkedIn, at a recent SRE Meetup in Bangalore. Ponmani gave an insightful talk on "Improving data redundancy and rebalancing data in HDFS." We were cap