1: Critical alerts arrived as Slack messages that had to be spotted rather than answered
2: Pod-wide on-call sent alerts to engineers who did not own the failing service
3: One escalation policy applied to every monitor, regardless of business impact
4: A P0 response time the team could see but could not tighten
Solution
1: Severity-based paging, so only critical alerts become an incident on a five-minute P0 window
2: Service-level on-call rotations that page the engineer who owns the service
3: Escalation policies weighted to what an incident can cost the business
4: Slack visibility for the engineering lead, with no pager to carry
How PopClub turned Datadog alerts into incidents that reach the right engineer within seconds
How PopClub turned Datadog alerts into incidents that reach the right engineer within seconds
Good monitoring answers one question: is something broken. It does not answer the second one, which is who should pick this up right now.
PopClub is a rewards UPI payments app and a Razorpay company. Mohan Kumar Pandian leads the engineering team, with backend leads Ankur and Shivam running the pods under him. They have run Datadog for observability for a while, and the monitors are solid. Severity tiers are clean. Alerts fire when they should.
The gap in the stack was never detection. It was what happened to an alert after it fired.
For a year, Datadog sent every alert into Slack as a message across three states: warning, critical, and recovery. The team had full visibility. What a Slack message cannot do is interrupt you. When a payments-down P0 lands in the same channel as a routine warning, it reads like any other line until someone scrolls to it, and on a payments app, the minutes spent scrolling are minutes customers feel.
This is the coordination problem every fast-moving SRE team meets sooner or later. Monitoring gives you a clean signal. Deciding which signals deserve a human, and getting each one to the person who can actually act, is a separate discipline that a monitoring tool was never built to run.
"Whenever an alert fires from Datadog, the webhook triggers and whoever is on call gets the alert. That is the basic rule we follow."
Mohan Kumar Pandian, PopClub
Under 1 minDatadog alert to incident, often seconds
10 to 15 minP0 acknowledgment
30 to 60 minTypical P0 recovery
Under 2 hrsAverage recovery on harder cases
Xurrent IMR became the layer that sorts each alert by impact and routes it to the engineer who owns the fix
PopClub added Xurrent IMR on top of Datadog and used it to make three decisions that Datadog alone was not going to make for them.
01
It decides which alerts interrupt a human.
Monitors are sorted P0, P1, and P2 by business impact. Everything still flows to Slack for visibility, so nothing is lost. Only a critical alert crosses the threshold into an incident, on a five-minute P0 window. The noise stays in Slack where it belongs, and the alert means something again.
02
It decides who gets the alerts.
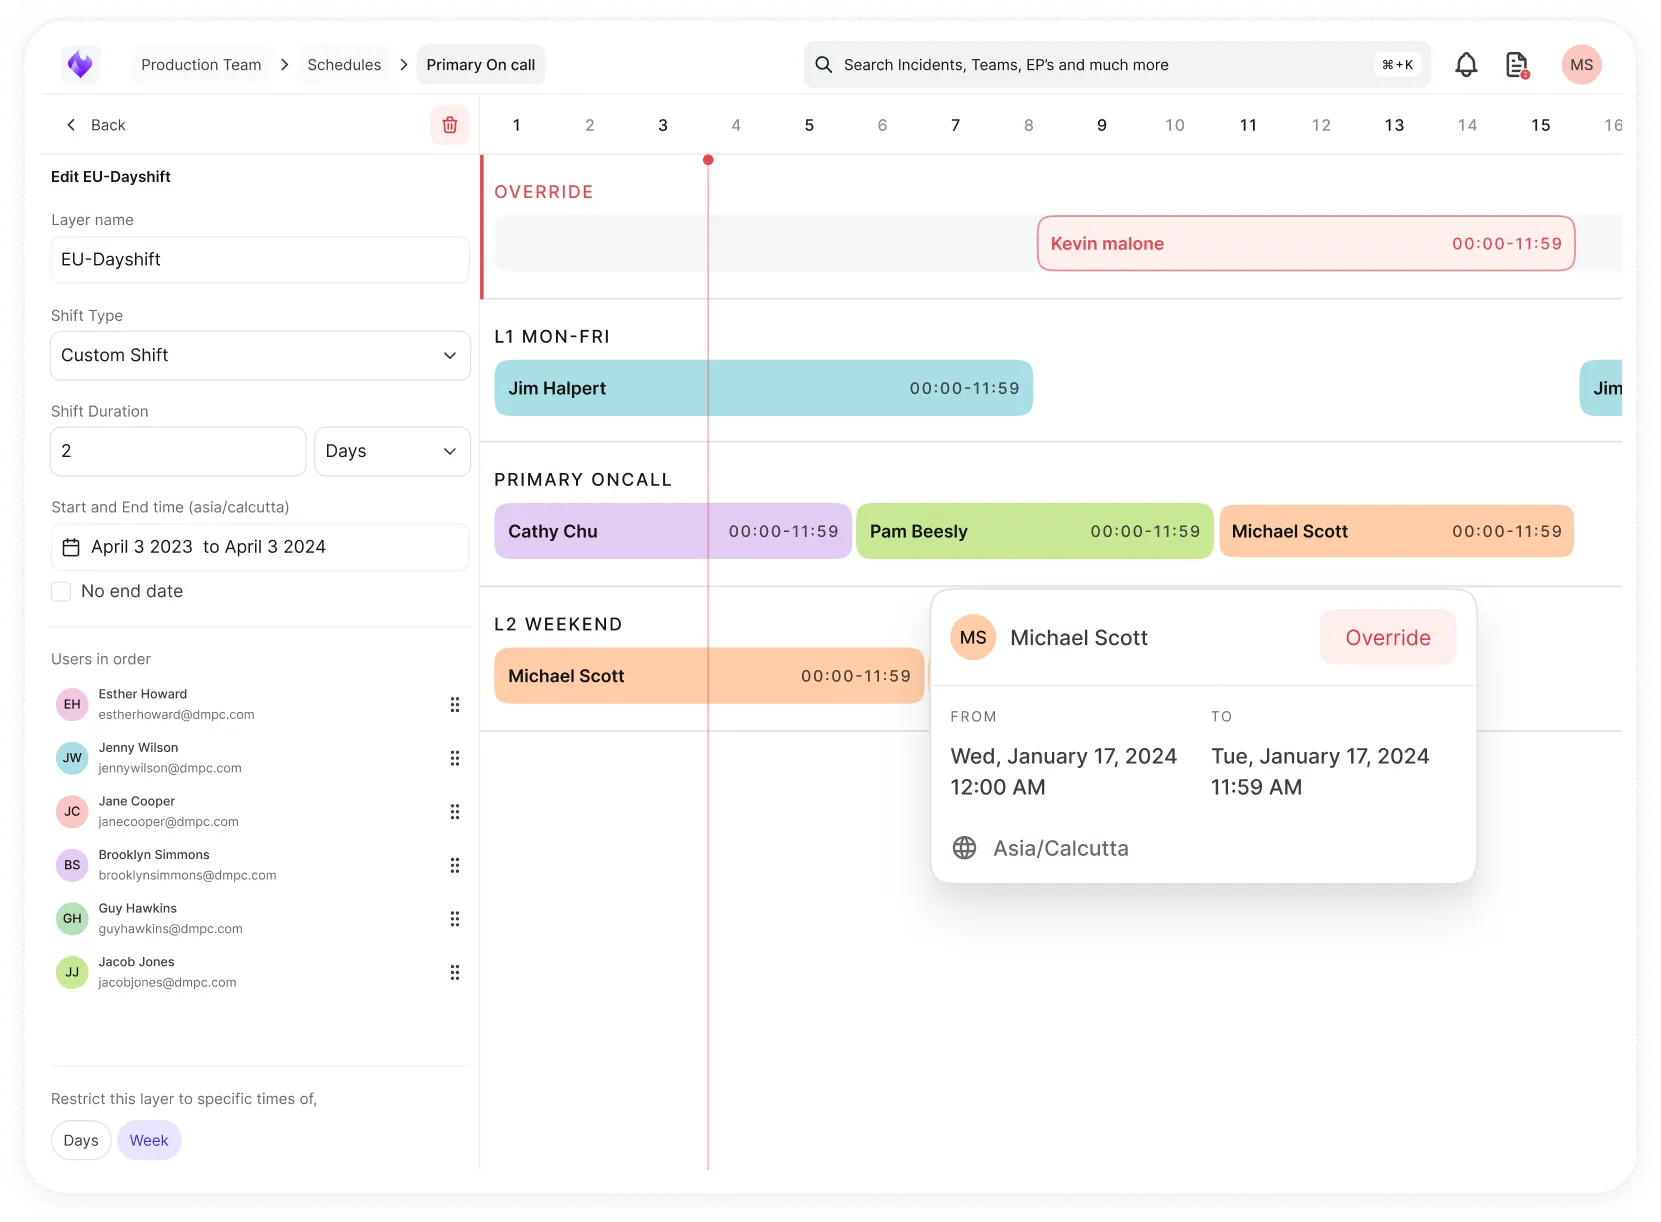
PopClub's pods each own several services, and every service has an owner who holds the context. The team split on-call along those lines. Each owner now has their own rotation and their own escalation policy, so an alert for a payments service reaches the person who built it. The old pattern, where whoever held the pod pager could get an alert for a service they had never touched, acknowledge it, and then hand it to someone with context, is gone.
The tradeoff
That tradeoff is worth stating. It works because service ownership at PopClub is real and current. A team without that would need to fix ownership first, or fine-grained rotations turn into upkeep.
03
It decides how hard to escalate.
A single escalation policy for every monitor is a decision made by not making one. PopClub weighs escalation by impact. Low-priority monitors escalate gently. High-impact ones escalate hard, so if the first responder misses it, the next engineer is minutes away and a serious incident cannot sit unacknowledged while it spreads. Mohan stays out of the rotation and never carries a pager, but he sees every incident through Slack, so he gets oversight without the 3am noise.
"Now I can assign a service or cluster-level on-call, and that person gets the alerts and can solve it very fast. We tried it recently and it is working pretty fine for us."
Mohan Kumar Pandian, PopClub
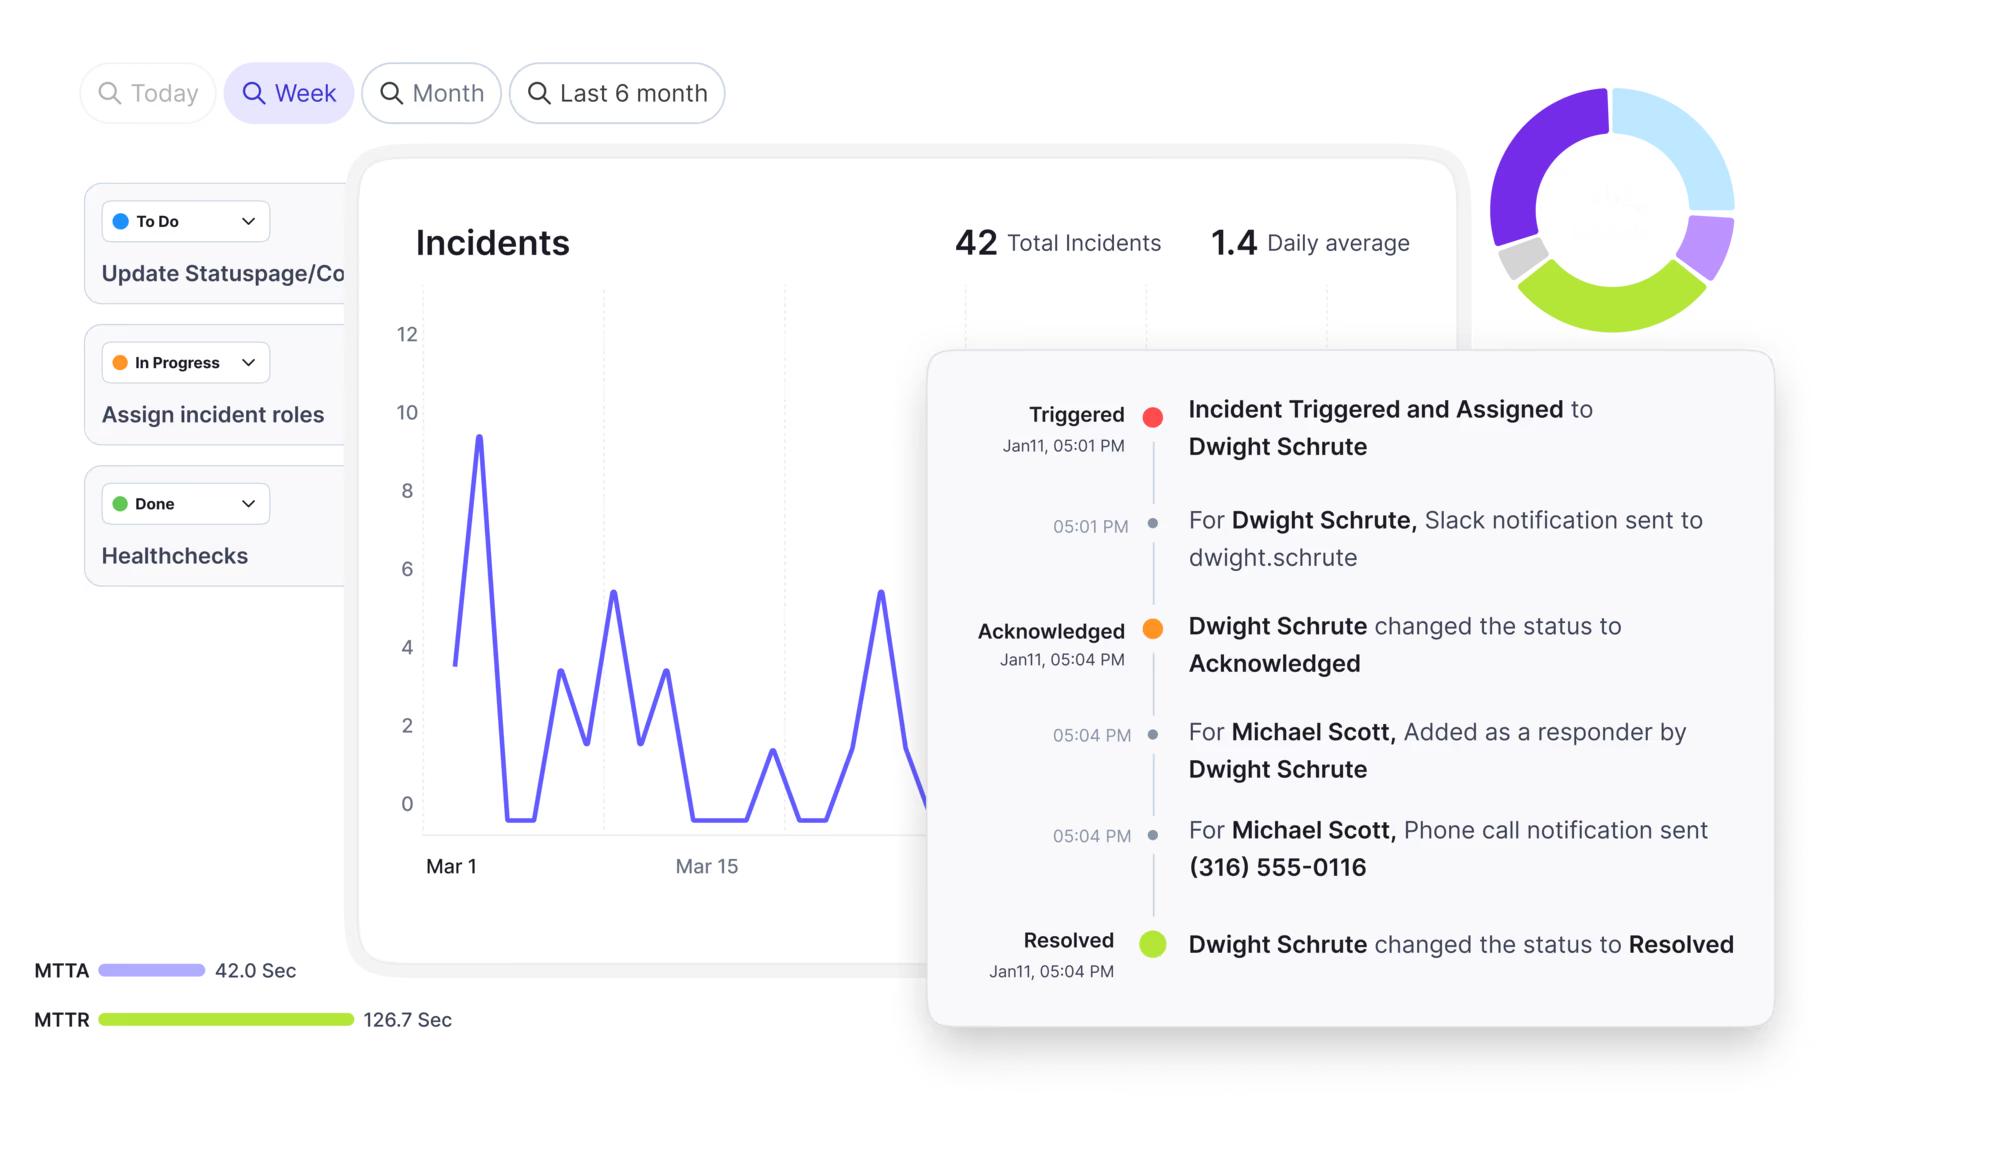
The handoff from a Datadog alert to an incident now takes under a minute
Detection is the number PopClub watches most closely, and it is where Xurrent IMR earns its place. Datadog already burns a confirmation window before it fires, three to five minutes on some monitors. Anything the handoff adds lands on top of a clock that is already running, so the team guards it.
"There are no lags. If Datadog triggers an alert, within a second we are getting the alert from Xurrent IMR, and that saves us a lot of time during the critical first minutes of an incident."
Mohan Kumar Pandian, PopClub
Detection and response live in Xurrent IMR
PopClub keeps a clean line between the two tools. Xurrent IMR handles detection and routing. The incident carries just enough signal to make a first call: the affected API groups or service, the latency or error-rate impact, and the service name. From there the engineer opens Datadog and traces it. For anything with a wide blast radius, the team spins up a Slack channel with a Meet link and pulls responders in by hand.
"All the data needed for the judgment is what we try to pass in the alert. The developer then goes to Datadog, because that is where the entire implementation after root cause analysis happens."
Mohan Kumar Pandian, PopClub
Metric
Result
Datadog alert to incident
Under 1 minute, often seconds
P0 acknowledgment (MTTA)
10 to 15 minutes
P0 recovery (MTTR), typical
30 to 60 minutes
Recovery on a known revert
10 to 15 minutes
Average recovery, harder cases
Under 2 hours
Detect target the team is driving to
10 minutes
On-call model
Service-level ownership, escalation weighted by impact
Stack
Datadog for observability, Xurrent IMR for detection, alerting, and routing
Before and after, on the path an alert takes
Before Xurrent IMR
After Xurrent IMR
BeforeDatadog alerts arrived as Slack messages
AfterCritical alerts interrupt as an incident within a second of Datadog firing
BeforeOne shared channel, where a P0 looked like a warning
AfterSeverity decides incident versus message, on a five-minute P0 window
BeforePod-wide on-call, so alerts could miss their owner
AfterService-level rotations alert the engineer who owns the fix
BeforeOne escalation policy for everything
AfterEscalation weighted by business impact
BeforeThe lead tracked incidents from a console
AfterThe lead gets Slack visibility and carries no pager
What the team chose to keep after a year of real on-call
These are the features that survived real on-call at PopClub, not the ones in a pitch deck.
Configuration down to the service owner
This is the one Mohan names first. Who gets paged, which SLA applies, and how escalation runs are all set per service, and that granularity is what made the whole routing model possible.
"I can configure it down to the service owner. The SLAs, the escalation policies, the on-call, all set per service."
Mohan Kumar Pandian, PopClub
Integrations that stay out of the way
Slack and Datadog plug in cleanly, and as a lead, Mohan does not need to live on the platform. The work happens on it and reaches him off it.
Alert sounds the floor learned to read
The team set up deliberately funny page tones, so the sound itself tells the floor an incident is live before anyone reads a word. It used to be one flat tone for everything.
Where PopClub is taking this next
The backend team is heavily on the platform now, at 25 engineers. Front-end is next. PopClub is wiring its RUM signal so that a crash-rate spike or an unresponsive app maps to the right pod and raises a page, the same way backend does today. When that lands, 40 to 45 developers will be on the platform, with another 10 to 15 covered through escalation, for roughly a 60-person presence.
Today25Backend engineers on the platform
Next40 to 45Developers once front-end RUM signals page the right pod
Full reachAbout 60People, with 10 to 15 more covered through escalation
The targets tighten with scale. PopClub is driving MTTD toward 10 minutes for P0 issues and recovery toward sub-13 minutes on known reverts. For a consumer-facing payments app, every minute shaved off detection is a minute fewer customers spend unable to pay.
PopClub did not add monitors or headcount. They changed where alerts go. An incident instead of a message for anything critical. The service owner instead of the pod for anything routed. Escalation sized to what an incident can actually cost the business.
If your monitoring is already solid and your service ownership is clean, that is the place the fast wins are. Bring the observability you already trust. We will handle the part where the right person picks up.
Mohan Kumar Pandian
Tech Leader, PopClub
There are no lags. If Datadog triggers an alert, within a second we are getting the alert from Xurrent IMR, and that saves us a lot of time during the critical first minutes of an incident.